"Intelligence that waits for the cloud is intelligence that arrives too late."
The product needed instant AI-driven decisions on devices with limited power, memory and connectivity. Round trips to the cloud added delay, cost and privacy concerns.
We built an on-device AI stack that runs models directly on phones and edge hardware, delivering results in milliseconds, offline and without sending data to the cloud.
"Intelligence that waits for the cloud is intelligence that arrives too late."
The product needed instant AI-driven decisions on devices with limited power, memory and connectivity. Round trips to the cloud added delay, cost and privacy concerns.
Decisions needed in milliseconds.
Limited memory, compute and battery.
Sensitive data should stay on the device.
We designed a pipeline that takes a cloud-trained model and delivers it efficiently to the hardware people use.
Cloud-trained baseline
Quantise, prune, distil
Compile for target hardware
Real-time, offline
Test accuracy and latency
Staged, monitored updates
We built a toolchain and runtime that compress models to fit, delivering cloud-grade intelligence on the device in the user's hands.
Results in under 50 ms.
Works without a connection.
Safe over-the-air model rollouts.
Data stays on the device.
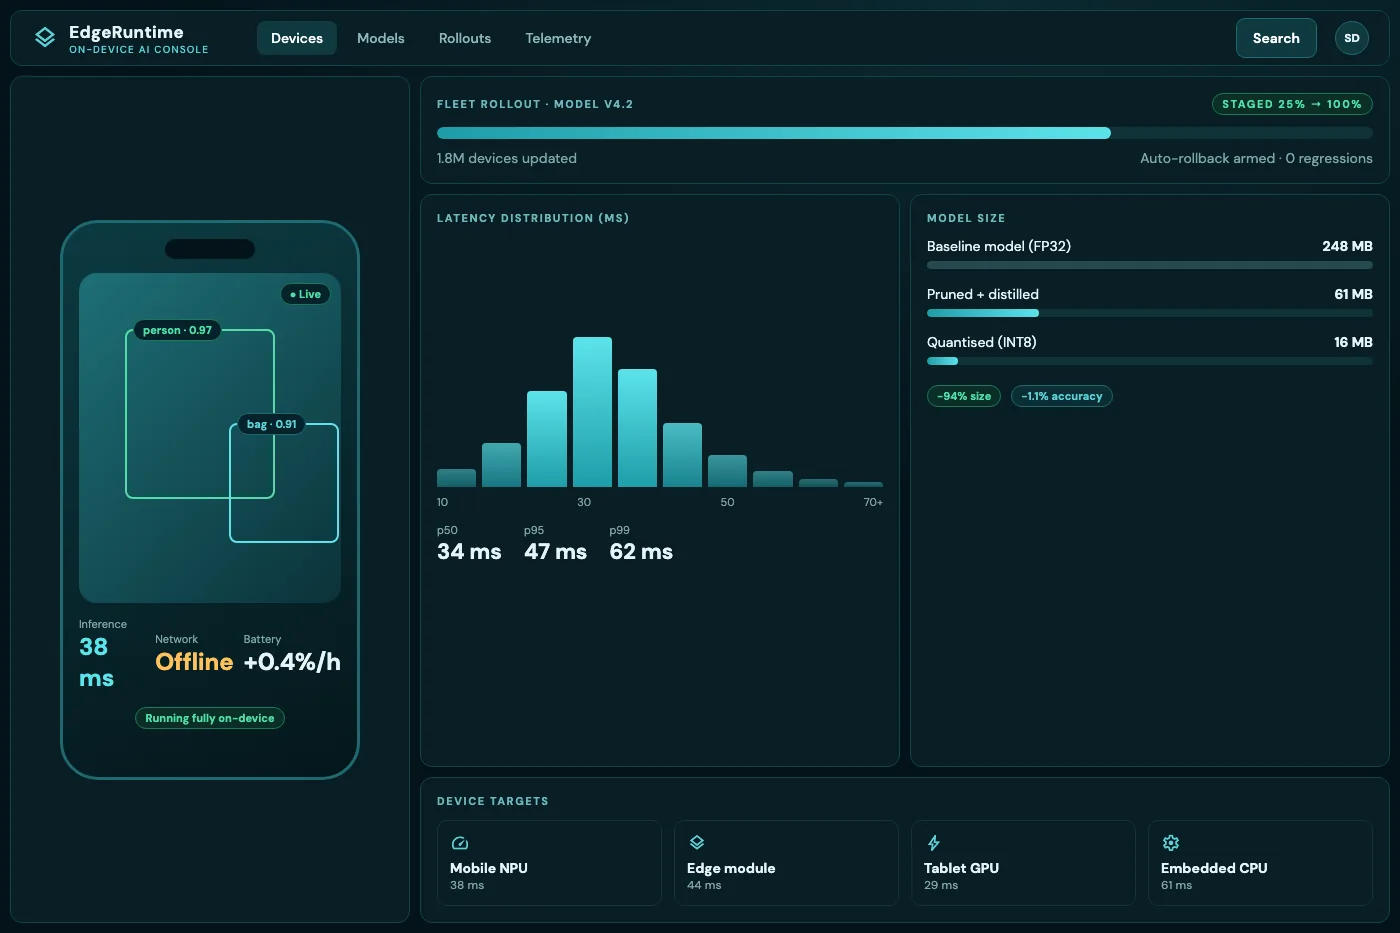
Our architecture spans the training pipeline to the device runtime: efficient, secure and portable across hardware targets.
Technical details
By combining model optimisation with real device constraints, we helped our partner achieve measurable improvements.
Fast enough to feel instant.
Full features without a connection.
Sensitive data never leaves the device.
The same product. The same users. A fundamentally better experience.
Early collaboration between ML and device engineers mattered most. Designing for the hardware from day one avoided rework and kept accuracy where users needed it.
The device's real limits.
ML and device teams together.
Optimise for the user's moment.
Tell us what you're trying to achieve. We'll help you explore the right approach from idea to impact.
View AllSend us the paragraph you'd normally write to a colleague. We'll get back to you within 24 hours.
hello@tathastha.com